


Sustaining product quality is a continuous journey. At NewStore, one of the key milestones in that journey was building a reliable and scalable testing infrastructure.
As our product and engineering organization grew, we discovered that reliable tests alone weren't enough. Scaling E2E testing wasn't just about adding more automation, it required clear ownership, visibility into coverage, and faster failure diagnosis.
For years, the mobile E2E test suite (iOS & Android) was a no-man’s-land. It lived in one folder, ran on one schedule, and broke on someone else’s merge request (MR). When it went red, the conversation in Slack started with, “Is this ours?” and ended, three hours later, with, “I think it’s fine—let’s rerun it.” Nobody owned it because everybody half-owned it.
The suite we run today looks nothing like that. Tests live alongside the teams that own the features, failures are automatically routed to the right squad with actionable diagnostics, and coverage gaps are continuously visible.
Over the past year, we:
Expanded automated end-to-end business journey coverage from 10 to 72 journeys
Grew the suite to 100+ E2E tests running across iPhone, iPad, and Android
Shifted E2E ownership from a central release team to the product teams responsible for Selling, HQ, Shopper, and FinOps
Achieved stable release-qualified E2E execution
Introduced AI-powered traceability and ownership, making coverage gaps, failing journeys, and responsible teams immediately visible
Reduced failure remediation time with AI-driven root cause analysis, flaky test recommendations, and actionable diagnostics, making E2E failures significantly easier to debug
These results didn’t come from simply writing more tests. They came from redesigning how ownership, automation, traceability, and diagnostics work together.
This is the story of how we built that system using Maestro for mobile test automation, Claude agents for AI-assisted failure diagnostics, and a small amount of glue code that turns three critical signals: what was tested, what failed, and who owns it , into something a team can act on without a meeting.
What E2E actually buys you
Scaling a team-owned E2E platform starts with understanding what E2E is uniquely responsible for. Unlike unit or component tests, E2E verifies the only thing that ultimately matters: whether a real user can complete a business journey across screens, network calls, and platform-specific behaviour on both simulators and real devices.
The trade-off is real: E2E tests are slower and more expensive than the rest of the Test Pyramid, but they’re also the only tests that prove a real user can complete a business journey on a real device.
Step 1: Tests live where the features live
The first thing we changed had nothing to do with AI. We split the suite by domain/team.
├── selling/ # Team Selling
├── shopper/ # Team Shopper
├── hq/ # Team HQ
└── finops/ # Team FinOps
Every test belongs to one of those subdirectories. Every test has three required tags: a team tag (selling, shopper, hq, finops), a stability tag (release or unstable), and platform tags (ios, android, or both). CODEOWNERS routes the directory to the team. When a test is reviewed, the owning team is notified. When a test fails in CI, the same team is automatically tagged in Slack with a link to the failing run and logs.
It sounds trivial. It wasn’t. Re-homing 200-odd tests is a slog, and the temptation to keep “shared” tests in a neutral folder is real. We resisted it. If a flow truly spans two teams, one of them owns it, and the other gets pinged on changes, but it has a single owner. “Shared” means “nobody.”
This is the structural foundation the rest of the system rests on. Without an unambiguous owner per test, no amount of clever automation gets the notification to the right person.
Step 2: A Traceability report that surfaces what you don’t test
A small generator walks the Maestro suite and compares it with each team's feature catalog. It produces a single HTML report showing coverage, missing journeys, obsolete tests, and long-running unstable scenarios.
Figure 1: AI-generated E2E traceability report showing scenario ownership, coverage, CI health, and device-level test distribution across teams.
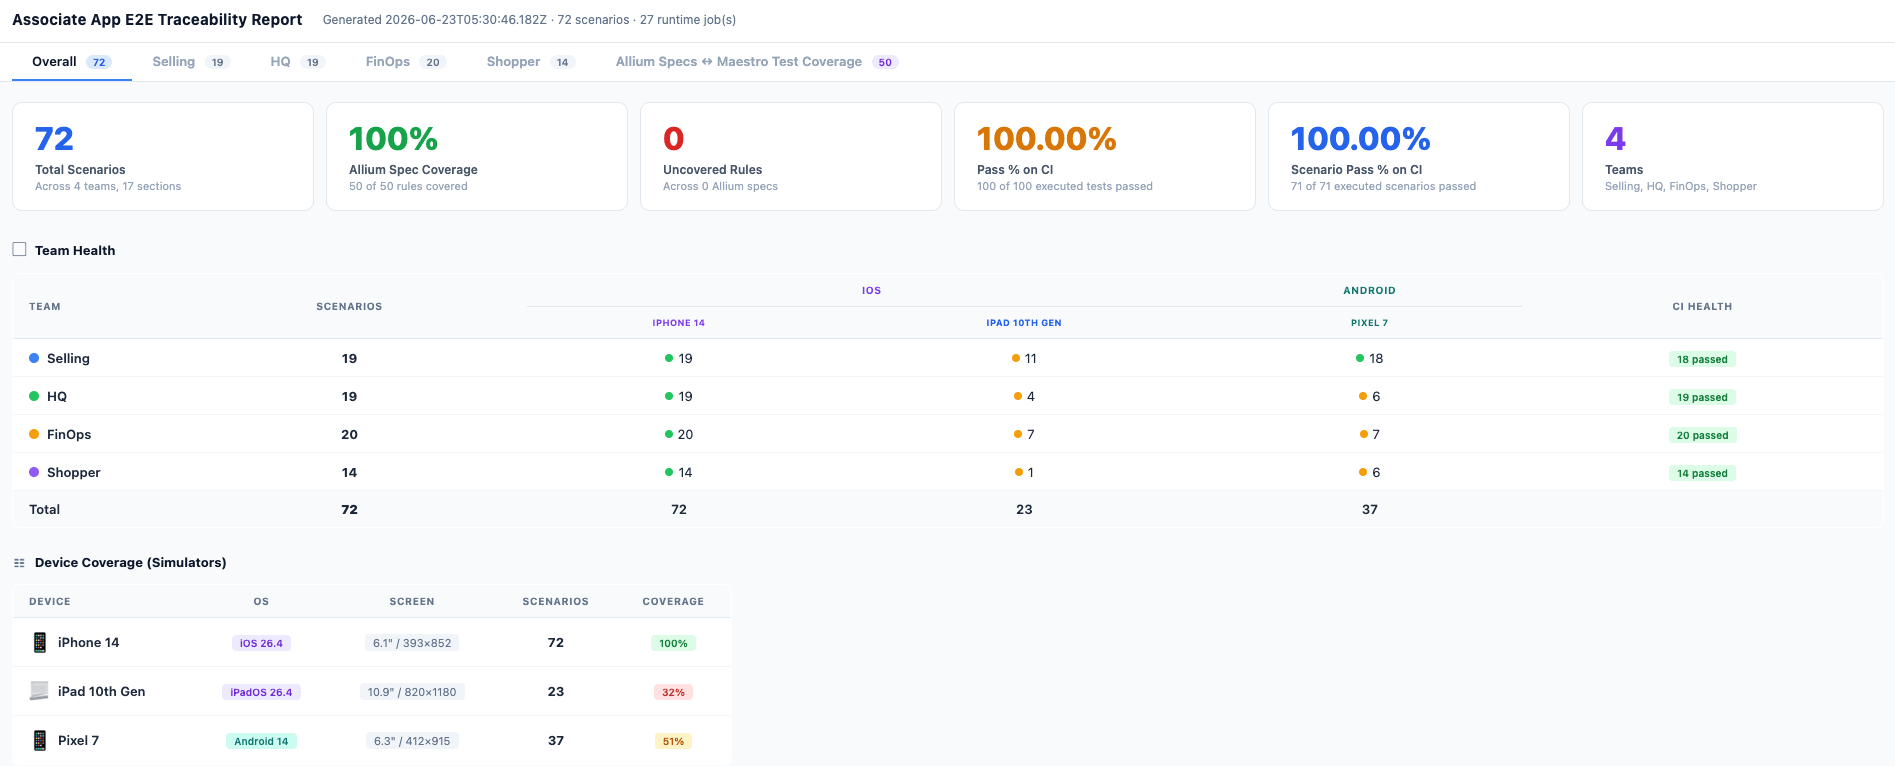
For each team, it highlights:
which user journeys are covered by at least one test?
which journeys are listed in the team’s feature catalog but have no test (a gap)?
which tests reference a journey that no longer exists (broken reference)?
which tests are tagged unstable and how long they’ve been there (stability debt)?
Figure 2. AI-generated E2E traceability report. The report maps business journeys to Maestro E2E scenarios, displays executable test steps, shows platform coverage (iOS/Android), and highlights CI execution status for each scenario, giving teams clear visibility into ownership and end-to-end test coverage.
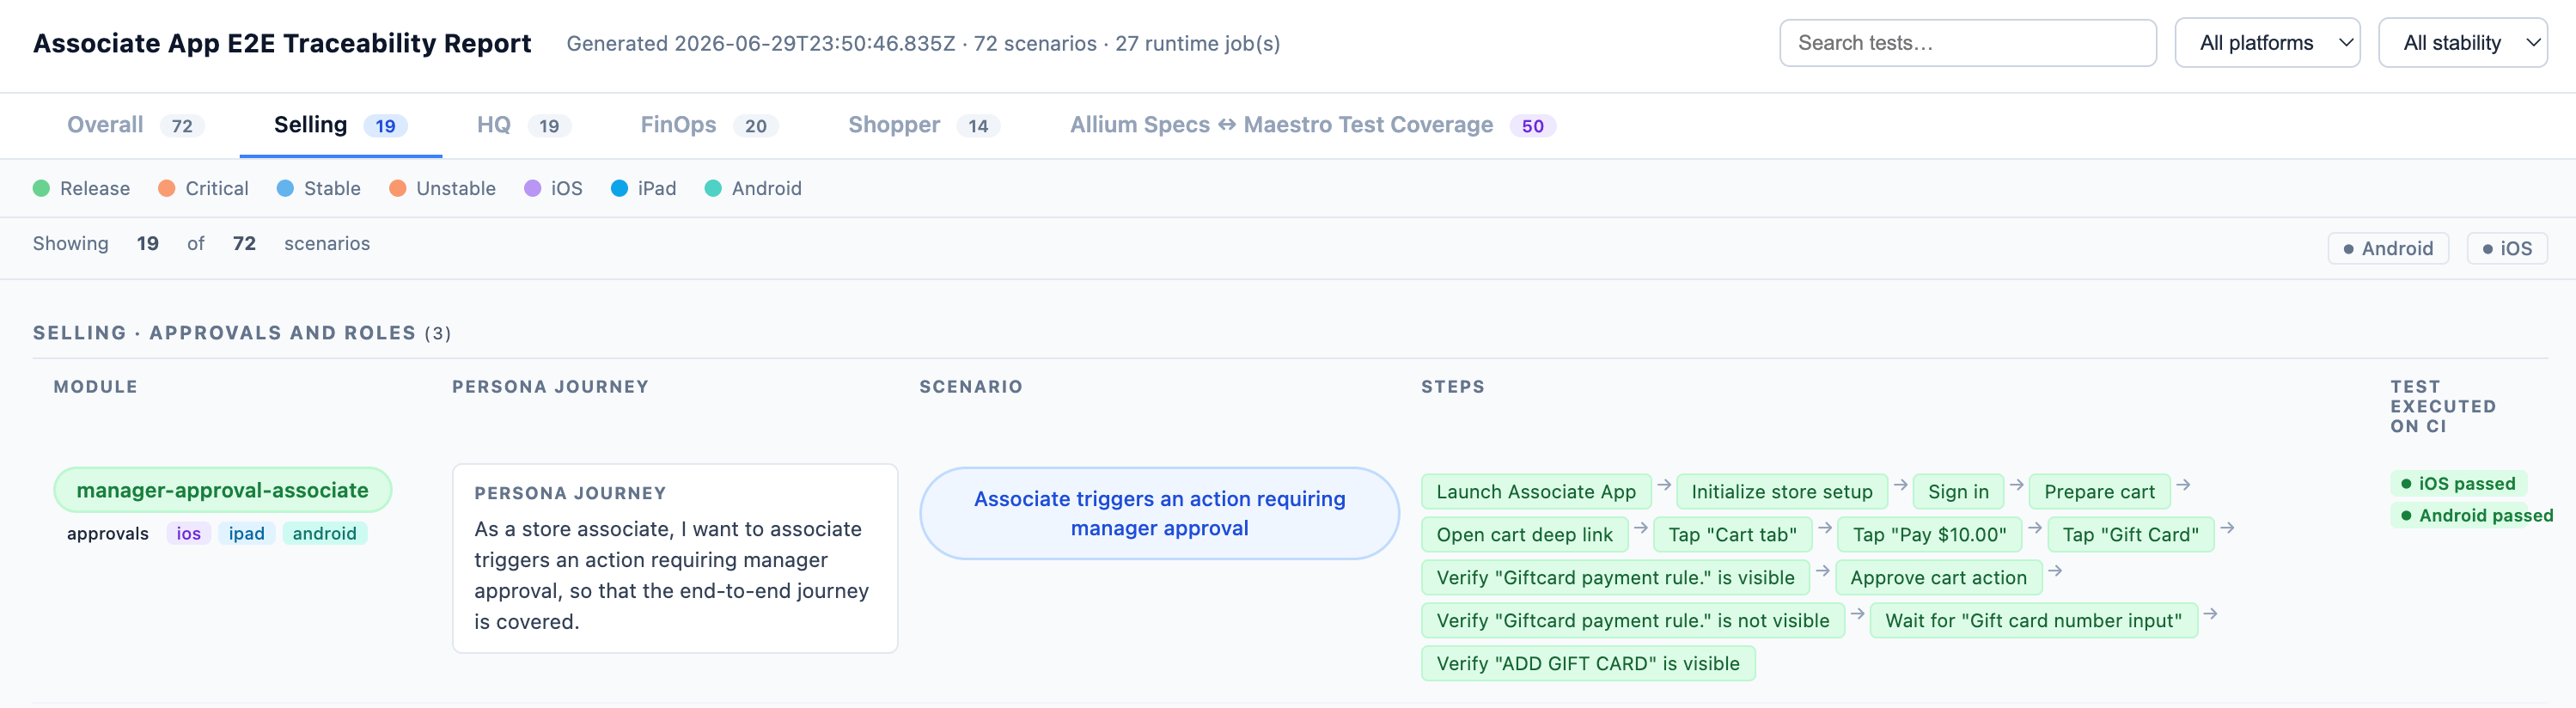
Coverage percentages tell you how much testing exists; uncovered journeys tell you where risk exists.
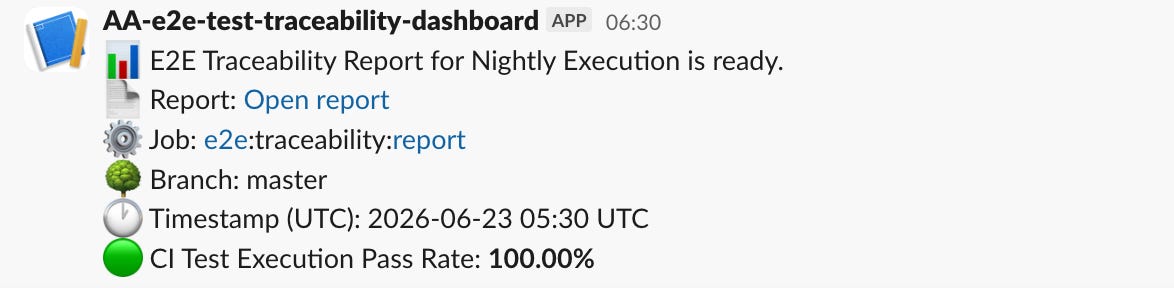
Every night, the report is published to Slack. Teams get an at-a-glance status indicator: 🟢 for 100% pass rate, 🟡 for less than 90%, and 🔴 for less than 80%, making regressions immediately visible.
Figure 3: Nightly traceability report notification posted to Slack, including CI pass-rate status
We don’t try to be clever about the feature catalog. It’s a plain YAML file each team maintains, listing the journeys they’re responsible for testing. Engineering owns the tests; product owns the catalog; the report joins them. Simple, transparent, and impossible to game.
Step 3: Failure triage with Claude + Maestro MCP
E2E failures look identical in a raw CI log, whether the cause is a real bug, a flaky selector, a missing fixture, a broken simulator, or a Maestro runner regression. Distinguishing them is mostly mechanical: open the artifact, look at the screenshot, check the view hierarchy, and compare it to the changed files. It's exactly the kind of constrained pattern-matching an LLM excels at—provided it operates within a well-defined workflow rather than improvising.
We built the triage path as a Claude skill (SKILL.md) that follows a deterministic workflow rather than relying on free-form reasoning.
Identify the failing job, platform, and exact failing spec.
Read the actual artifacts
report.xml,screenshots, view hierarchy,failed-tests.txt. No guessing from job names.Reproduce at the smallest safe scope, single spec first.
Resolve ownership from
CODEOWNERSbased on both the failing test path and the changed files.Classify into exactly one of five root causes: app regression, test runner issue, test script issue, environment, or test data.
Output a concrete next step: the rerun command, the likely fix, and the owning team.
When Maestro MCP is available, locally or in CI jobs, we explicitly wire it into the agent to go further. It boots a simulator through the MCP integration, reruns the failing spec, captures a fresh screenshot and live view hierarchy, and compares them to what the CI artifacts showed.
The most important constraint is honesty. If Maestro MCP isn't available or a rerun is inconclusive, the agent explicitly reports "artifact-only analysis." It never claims to have reproduced an issue without fresh evidence. That single rule keeps the diagnoses trustworthy enough for engineers to act on them.
Step 4: Notifications a team can actually use
The last mile of this pipeline is the notification. For years, our failure notifications were a red checkmark and a CI link. Engineers learned to mute them.
What lands in a team’s Slack channel now looks like this:
🔴 Maestro failure shopper/clienteling/remote-cart
Platform: iOS · Job: maestro-ios-mr#48217
Primary cause: test script issue
Evidence: selector `id:add-to-cart` not present at step 14
(renamed to `id:add-to-cart-button` in MR !12498)
Owner: @team-shopper (CODEOWNERS ∩ MR-changed-files)
Rerun: yarn test:e2e iPhone shopper/clienteling/remote-cart
Suggested fix: update selector or revert the rename
The routing that produces that message looks like this end-to-end:
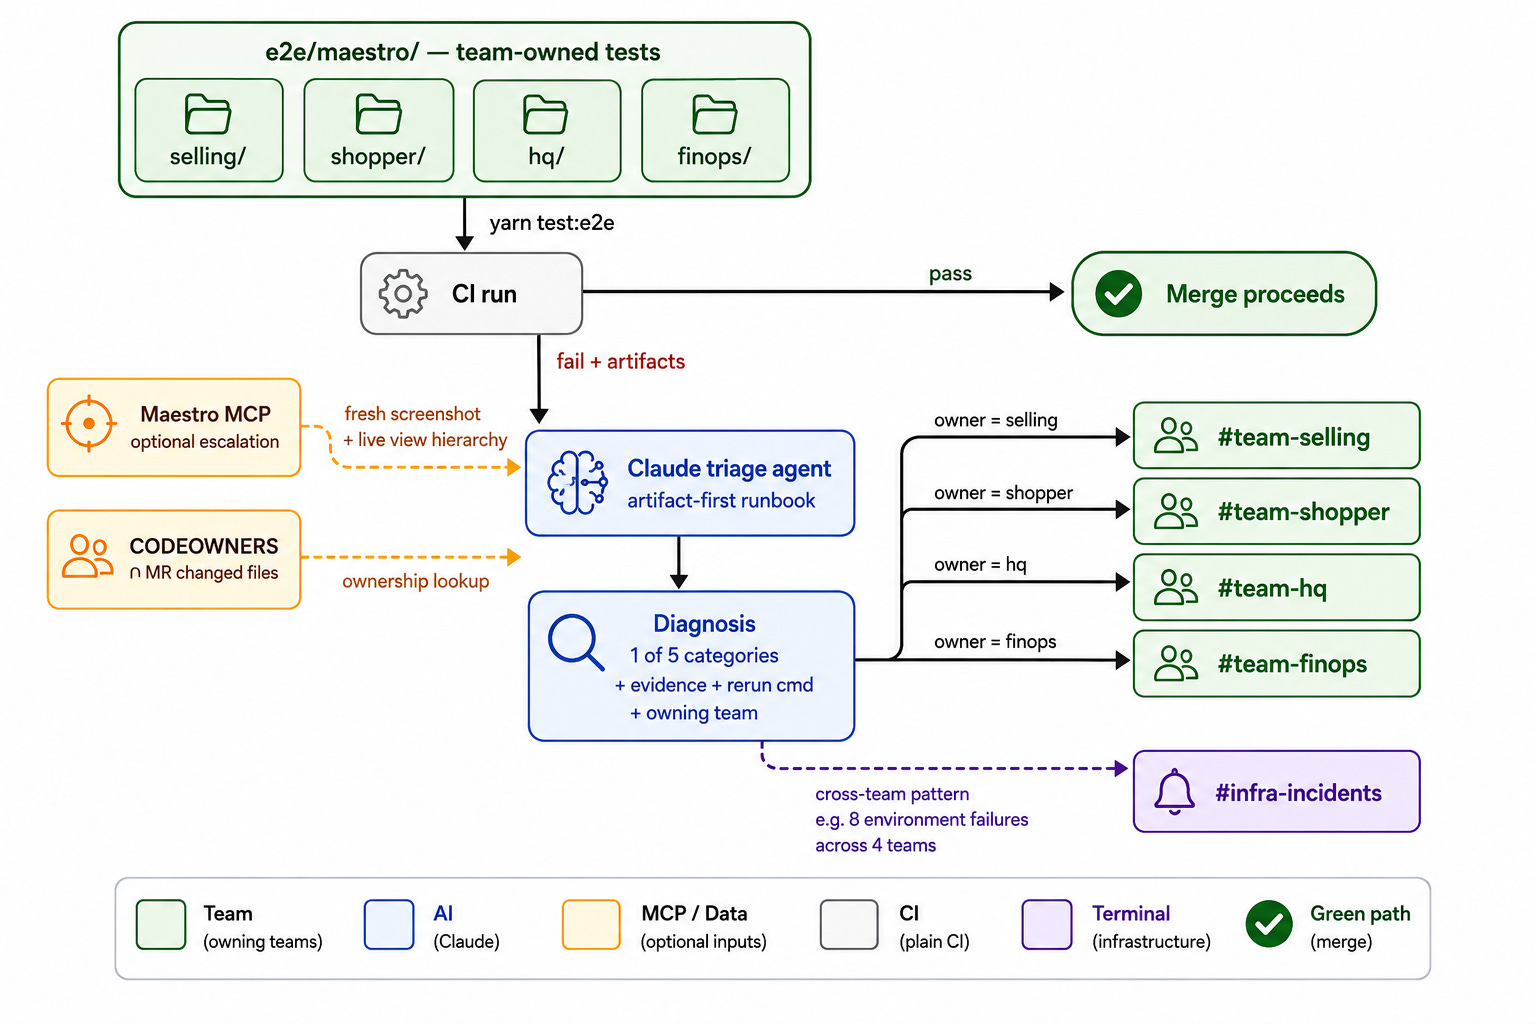
Three things are doing the work in the notification:
A classified verdict. “Test script issue” tells the on-call engineer this is theirs to fix, not an infra ping. If the verdict had been “app regression,” they’d know to check whether the MR change was intentional.
An owner the agent is committed to. No “could be either team” the intersection of CODEOWNERS and the changed files produced a single team. (When it doesn’t, the agent surfaces both candidates rather than picking wrong.)
A rerun command. Not “see the docs for how to rerun.” The exact command. Copy, paste, done.
Each team sees only their own failures, with enough context to act in under a minute. The shared channel still exists for cross-cutting incidents. When eight tests across four teams classify as "environment" in the same window, that's an infrastructure incident, and the pattern is visible because the labels exist.
How we keep flakiness from creeping back
It’s a category of test-script issues, and once the agent labels them as such, they have a fix path. The reason our suite stays stable isn't that we were careful when we wrote it—we weren't, the first time. It’s that we wrote down the practices th at produced flakes, and made the agent + tags + traceability report enforce them.
The concrete rules:
Selectors are IDs, not text. We started with accessibility (a11y) locators to stay close to how users interact with the app. As the suite expanded across iOS and Android, we found that stable
testIDs were more reliable and platform-agnostic for end-to-end automation. Every tappable element used in an E2E flow has atestID; if one doesn’t exist, we add it before writing the test. This keeps tests resilient to copy changes, translations, and dynamic content. We still use a11y locators extensively in component and domain-level tests as part of our TDD practices. For E2E tests, however,testIDs provide the most stable cross-platform selectors.
Waits target the next element, not “the animation.” We use extendedWaitUntil pointed at the specific element we need next. waitForAnimationToEnd is reserved for true post-animation cases (navigation push/pop, modal transitions) and always carries a comment explaining which animation it’s waiting for. No raw sleep. No blanket wait.
Assert before interacting. After navigation, we wait for the target element to be visible before tapping it. The tap that fails because the screen hasn’t rendered yet is the most common flake we used to ship.
Scroll explicitly before tapping anything below the fold. scrollUntilVisible with an id: selector never assumes layout. Devices with smaller screens are where unverified assumptions die.
Subflows are the canonical place for cross-cutting steps. Auth bootstrap, login, payment selection, cart setup, one subflow per concern. When a UI changes, the fix lands in one place, not eighty.
Wait for content, not the absence of spinners. extendedWaitUntil visible: id:target-element is reliable. notVisible: id:loading-spinner is a race.
Every test that creates data cleans it up. onFlowStart for setup, onFlowComplete for teardown, and onFlowComplete runs on failure too, which is the entire point.
No hardcoded prices, SKUs, or product names. Test data comes from env vars or _scripts/ setup. Hardcoded fixtures are the second-most-common flake source after timing.
retryTapIfNoChange: true is rationed. It’s allowed for known patterns (dismissing modals, list items still loading), and explicitly disallowed as a blanket “make this less flaky” tool. If a tap consistently needs retry, the selector is wrong, or the wait is missing, fix the cause, don’t paper over it.
Two structural things keep these practices from rotting:
The unstable tag has a two-sprint timeout. A test marked unstable is excluded from CI gating but tracked in the traceability report with its tag age. After two sprints, it’s fix-or-delete. No permanent quarantine, no “we’ll get to it later” tests sitting in the suite forever. The cost of leaving something broken is now visible; it has a name and a clock.
The agent’s “test script issue” verdict creates feedback pressure. When a flake gets classified three times in a row as a test-script problem, that’s a stack of evidence with a single owning team and a specific selector or wait at fault. Teams started fixing rather than rerunning because the rerun stopped being a free action; it left an audit trail.
The result is that our release-tagged suite runs green far more often than it used to, not because we eliminated flakes by hand, but because flakes now have somewhere to go: into a labeled category, into a team’s queue, with a deadline. The agent doesn't fix flaky tests. It makes them visible, classifies them consistently, and provides enough evidence that fixing them becomes straightforward
Conclusion
None of this happened because the AI is clever. It happened because the AI is consistent and fast at the boring parts: read the artifact, pick a category and because the structural choices around it—team-owned directories, required tags, and CODEOWNERS-backed routing—gave Claude a clean operating model.
A failing E2E test is no longer just a signal that something is broken. It's a well-defined piece of work with an owner, evidence, and a path to resolution.
Amazing framework. May i ask where is your agent hosted with the triage skill please